* 이제 Seedance 2.5를 1080p로 만들 수 있습니다. → updated 0814
* updated 0813 → 장면 구도별 표현까지 PDF파일안에 추가되었습니다. (글 하단)
* updated 08.11 → 가이드라인 PDF 파일이 추가되었습니다. (글 하단)
아무리 좋은 툴이어도 못쓰면 끝이니까.
요즘 seedance 2.5가 완전히 화재라는건 이제 다 아실겁니다. 여러가지 기능들이 추가된만큼. 아주 좋은 평가를 받고 있죠. 대표적 특징만 보면,
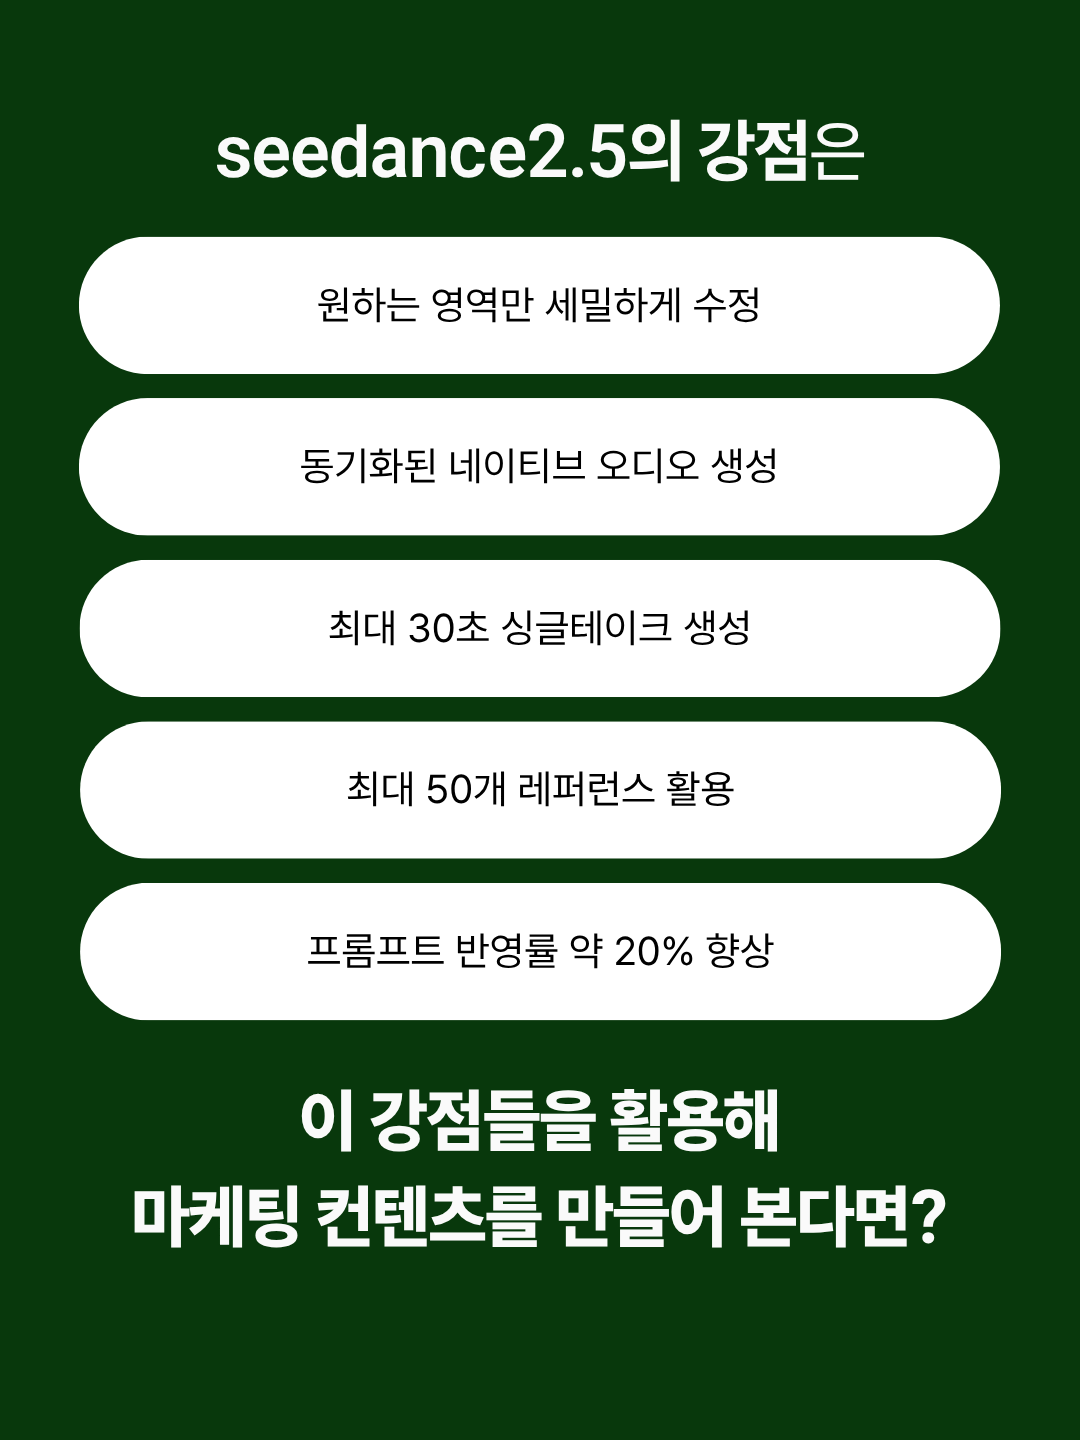
위와 같은 강점이 있다고 볼 수 있습니다. 이런 툴로 소상공인은 무엇을 만들어볼 수 있을까요?
이건 어떠세요?
그래서 한 번 생각해봤습니다. 과연, 소상공인 분들이 seedance 2.5로 어떻게 쓸 수 있을까? 그래서 이렇게 제안해봅니다.
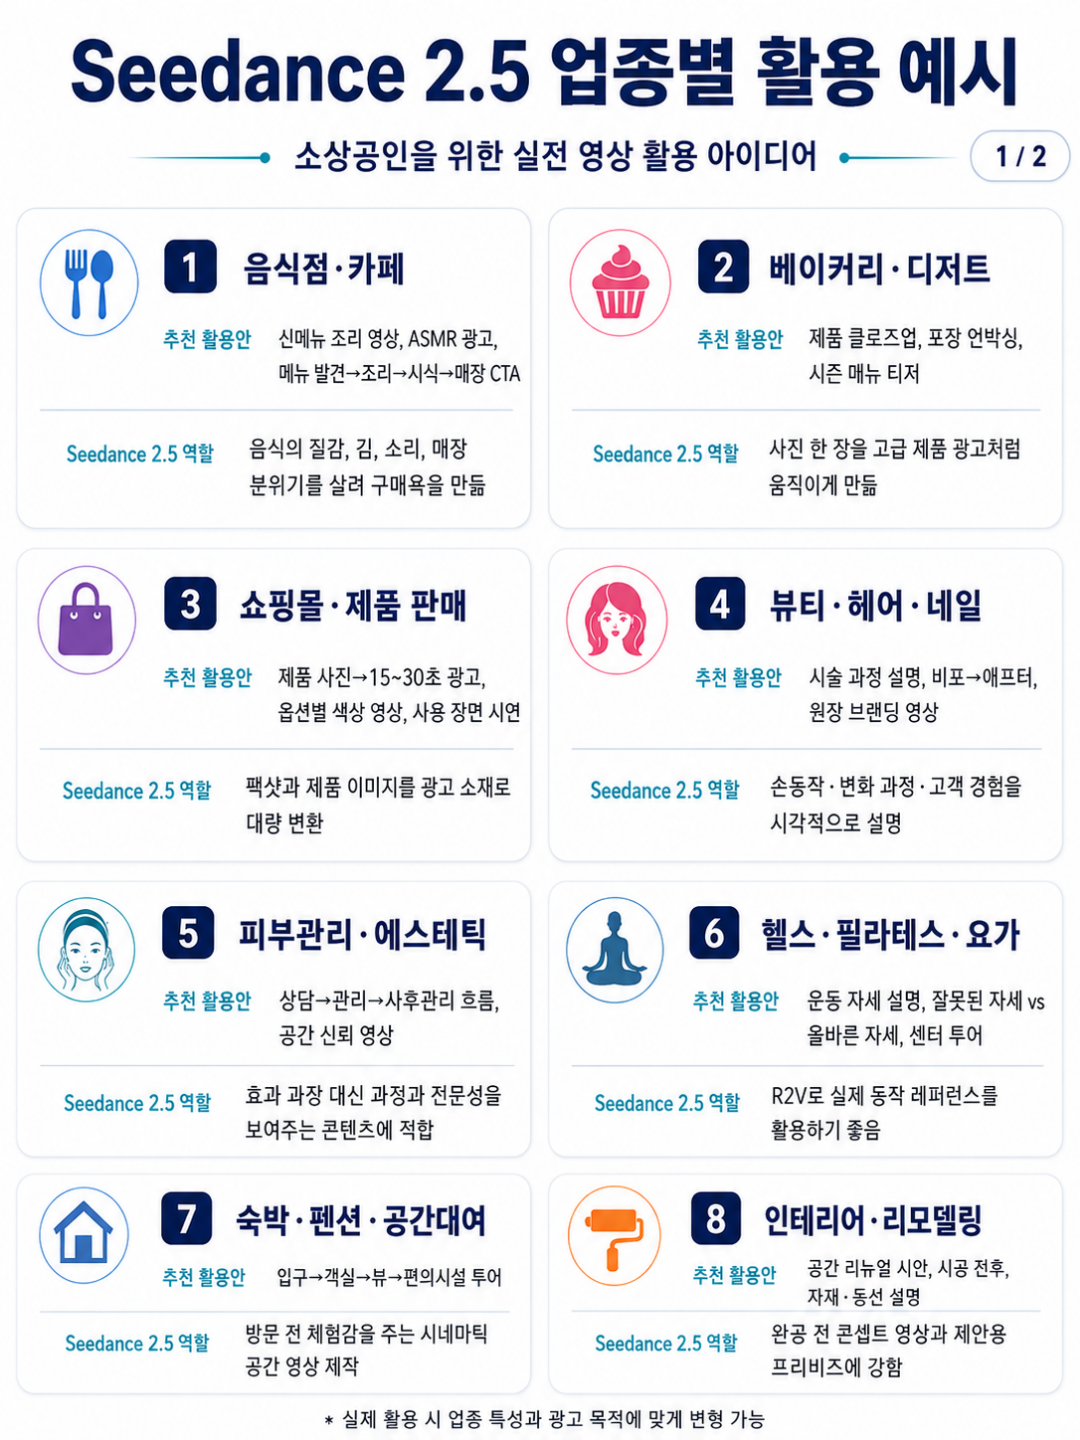
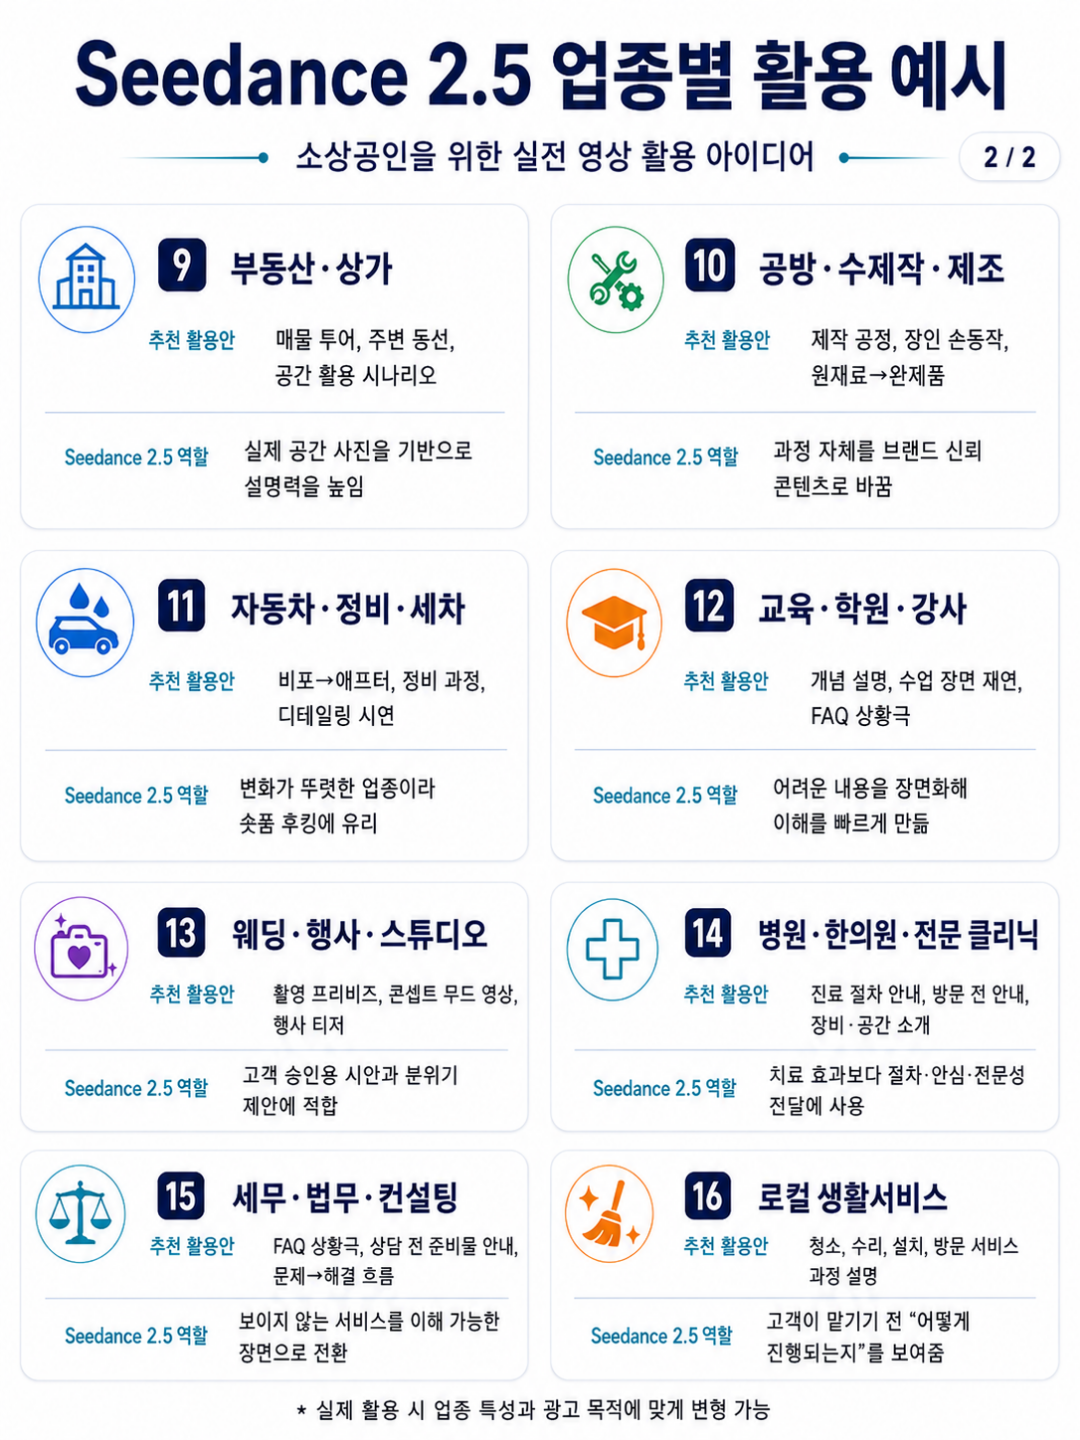
저도 2개 정도를 만들어봤습니다. 하나씩 보실까요?
1) 30초 원테이크 광고영상: 헬스장
원테이크 영상입니다. 이 영상은 총 7개의 레퍼런스 이미지를 가지고 만들었죠.
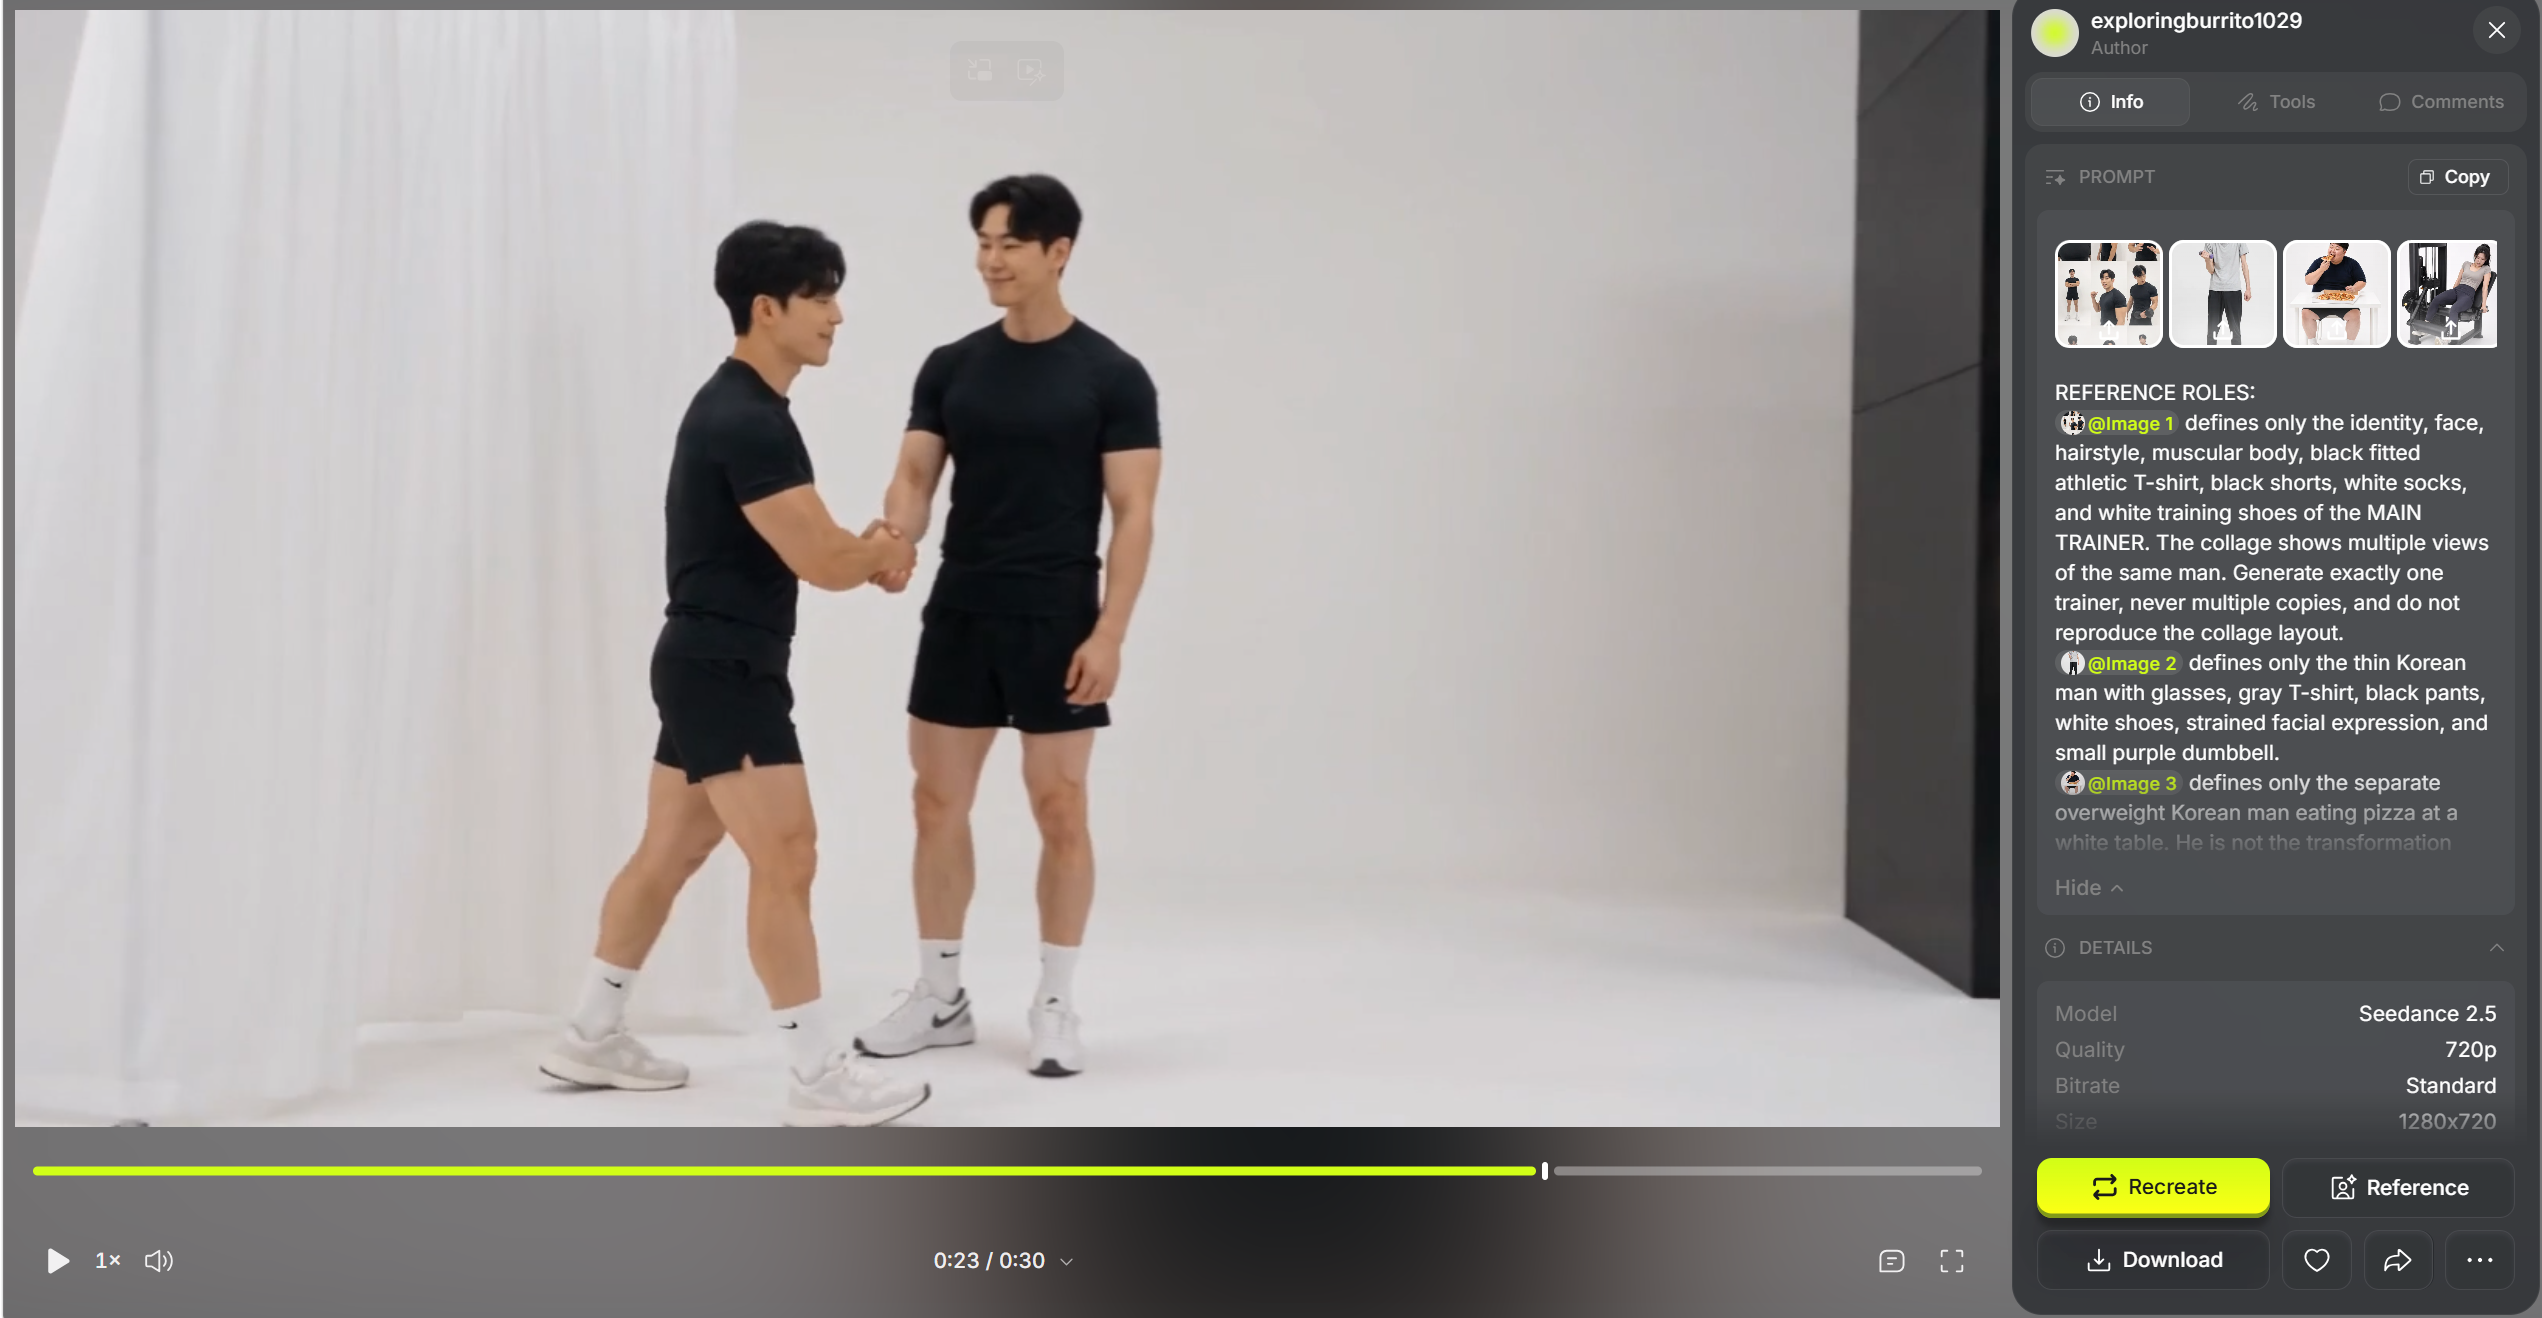
7장의 사진을 레퍼런스로 등록하고, 이 사진들을 하나씩 앵커링하여 프롬프트를 만들었습니다. 앵커링이란, 영상 제작을 위해 소스로 고정하는 과정으로 @를 써서 보통 지정합니다.
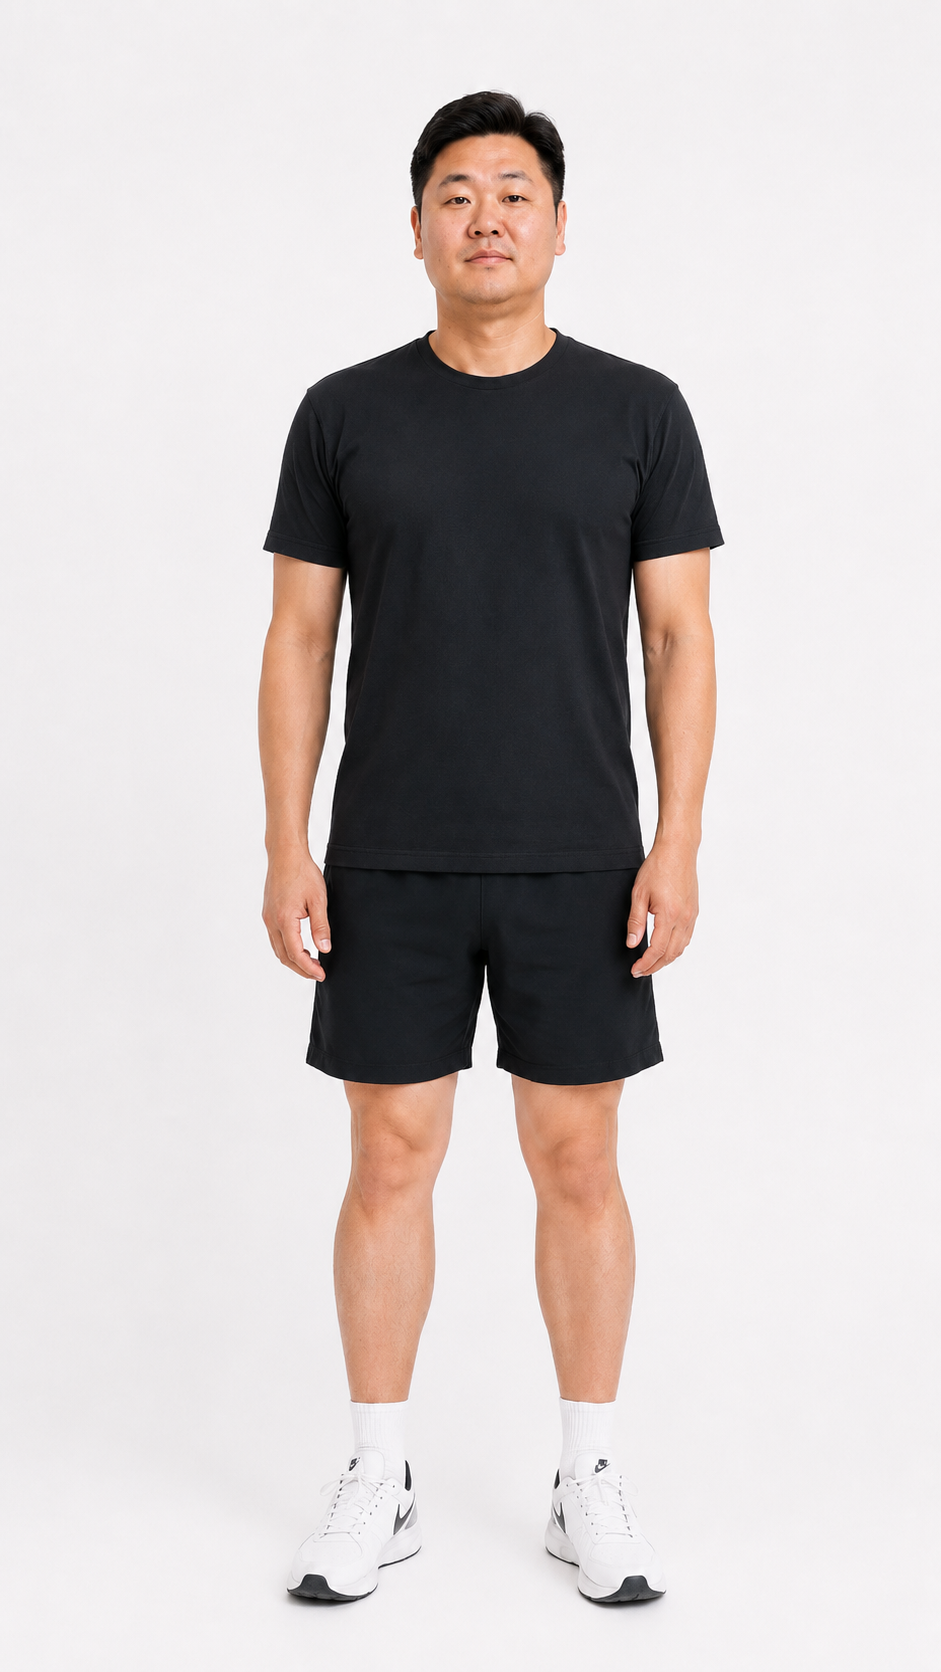
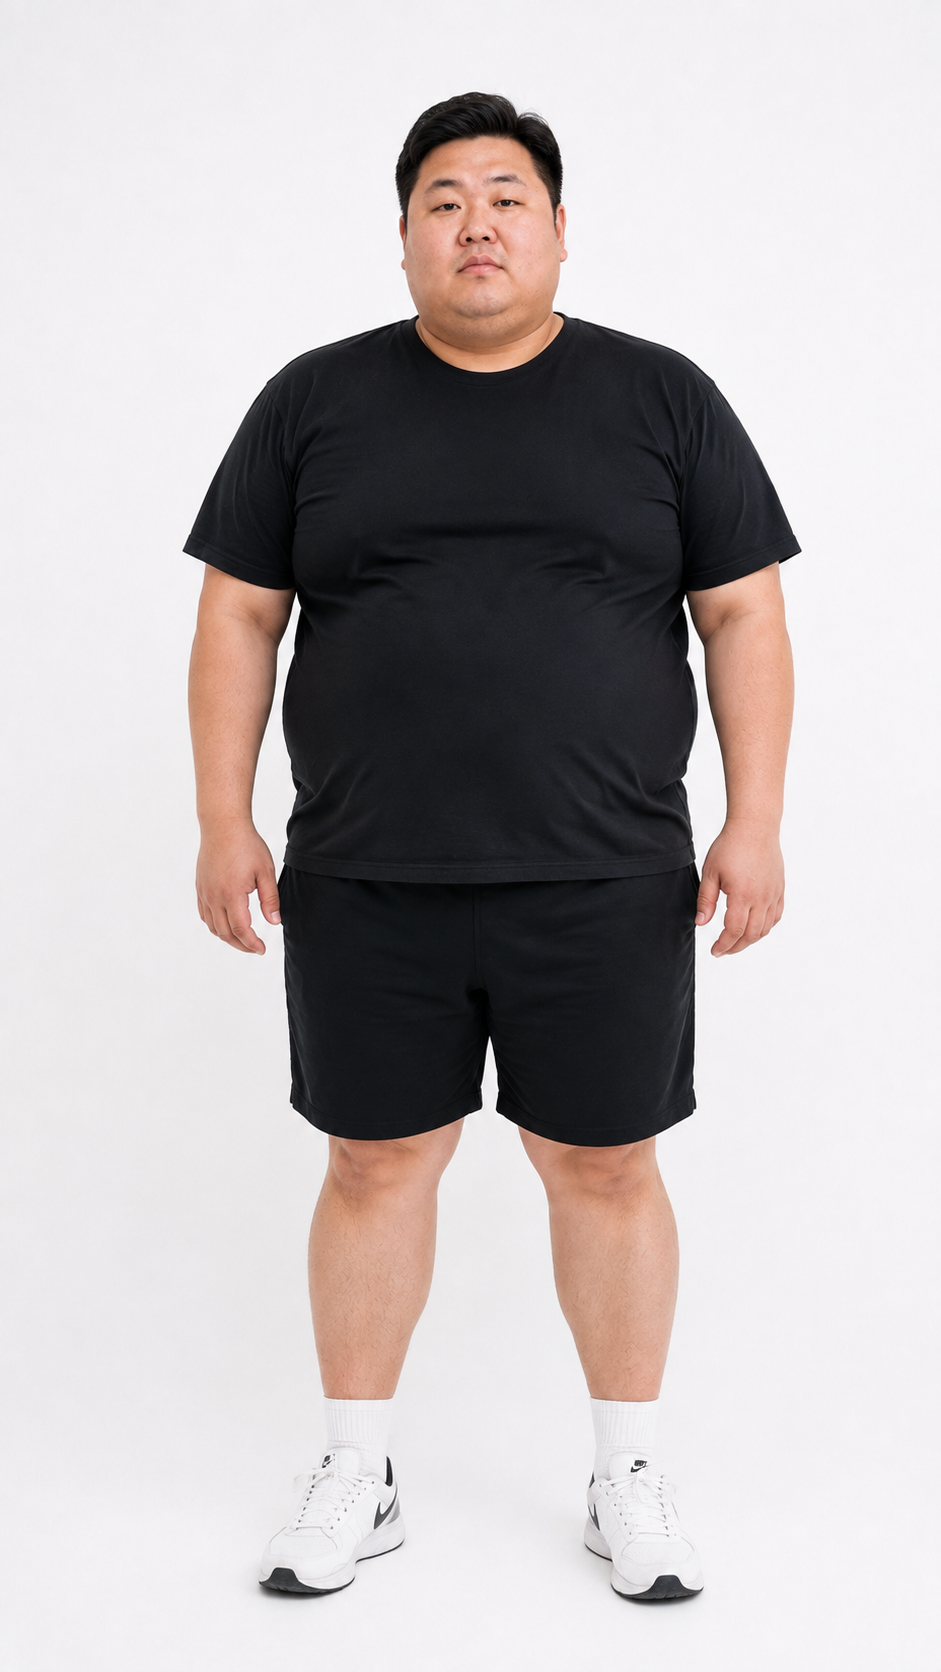
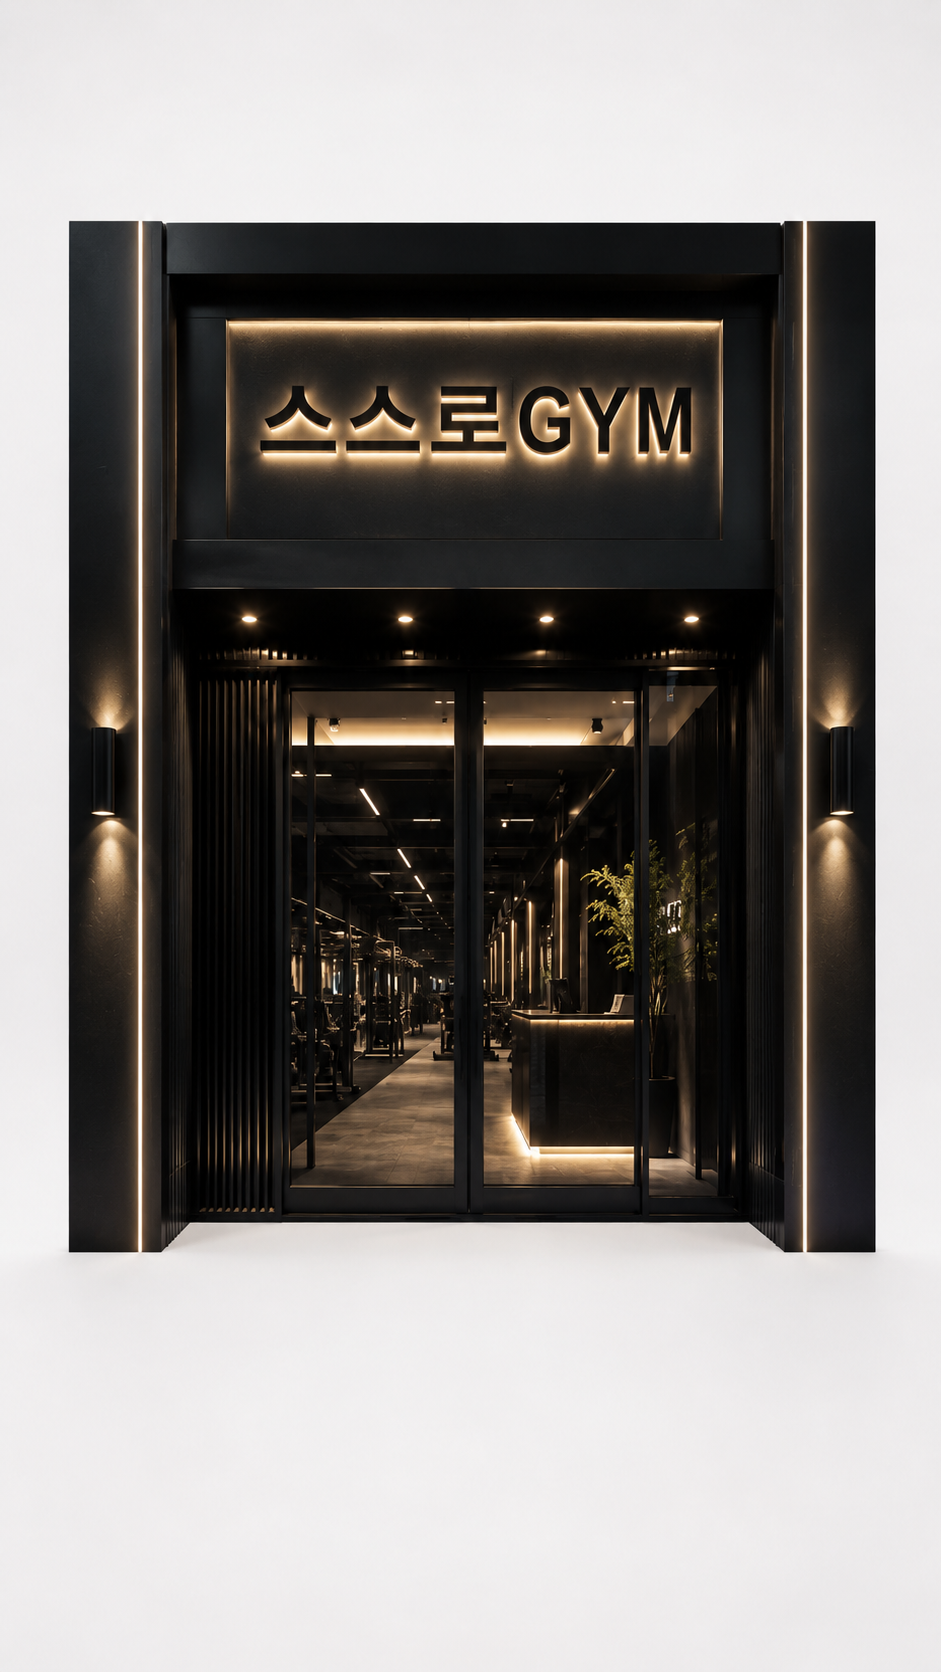
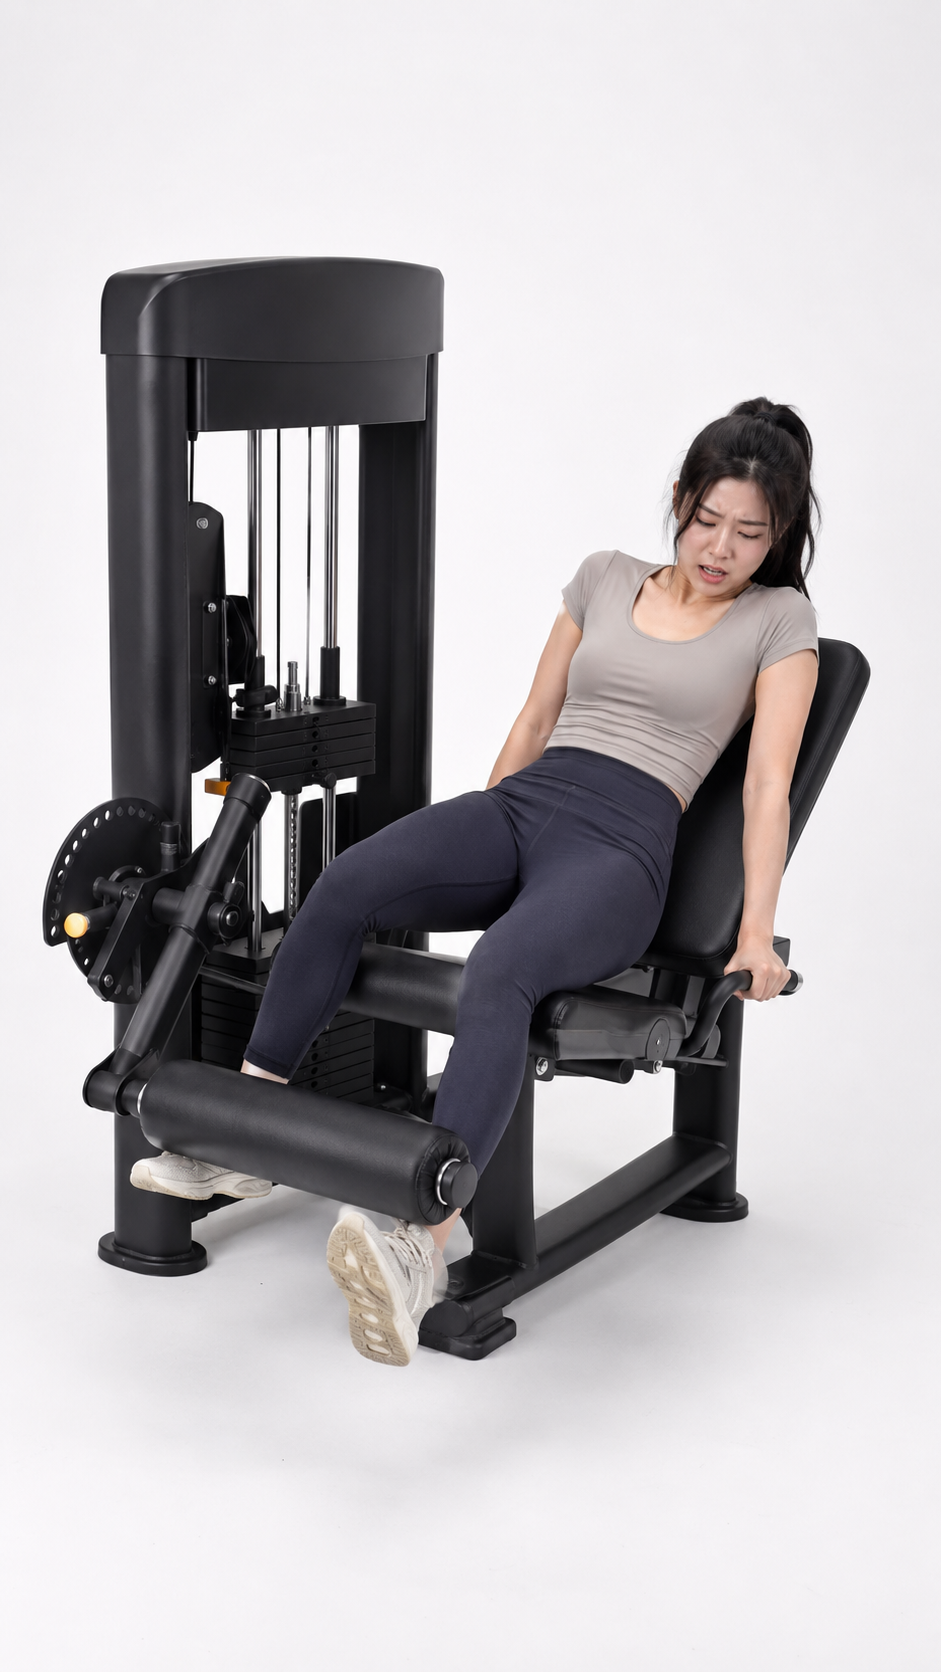
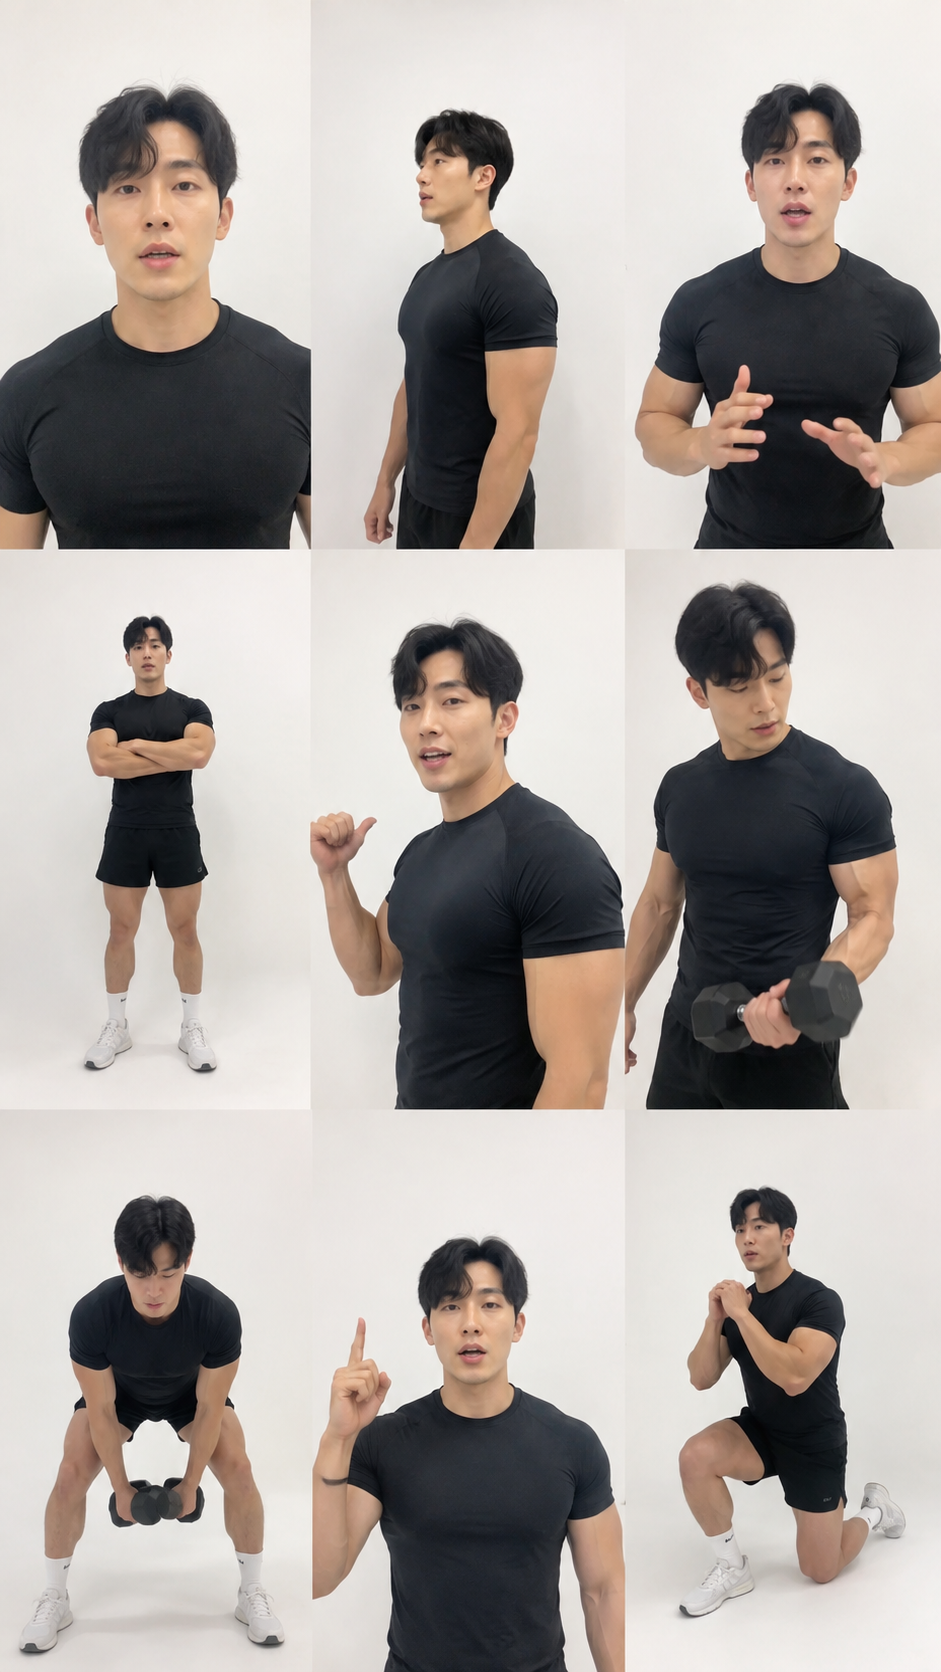
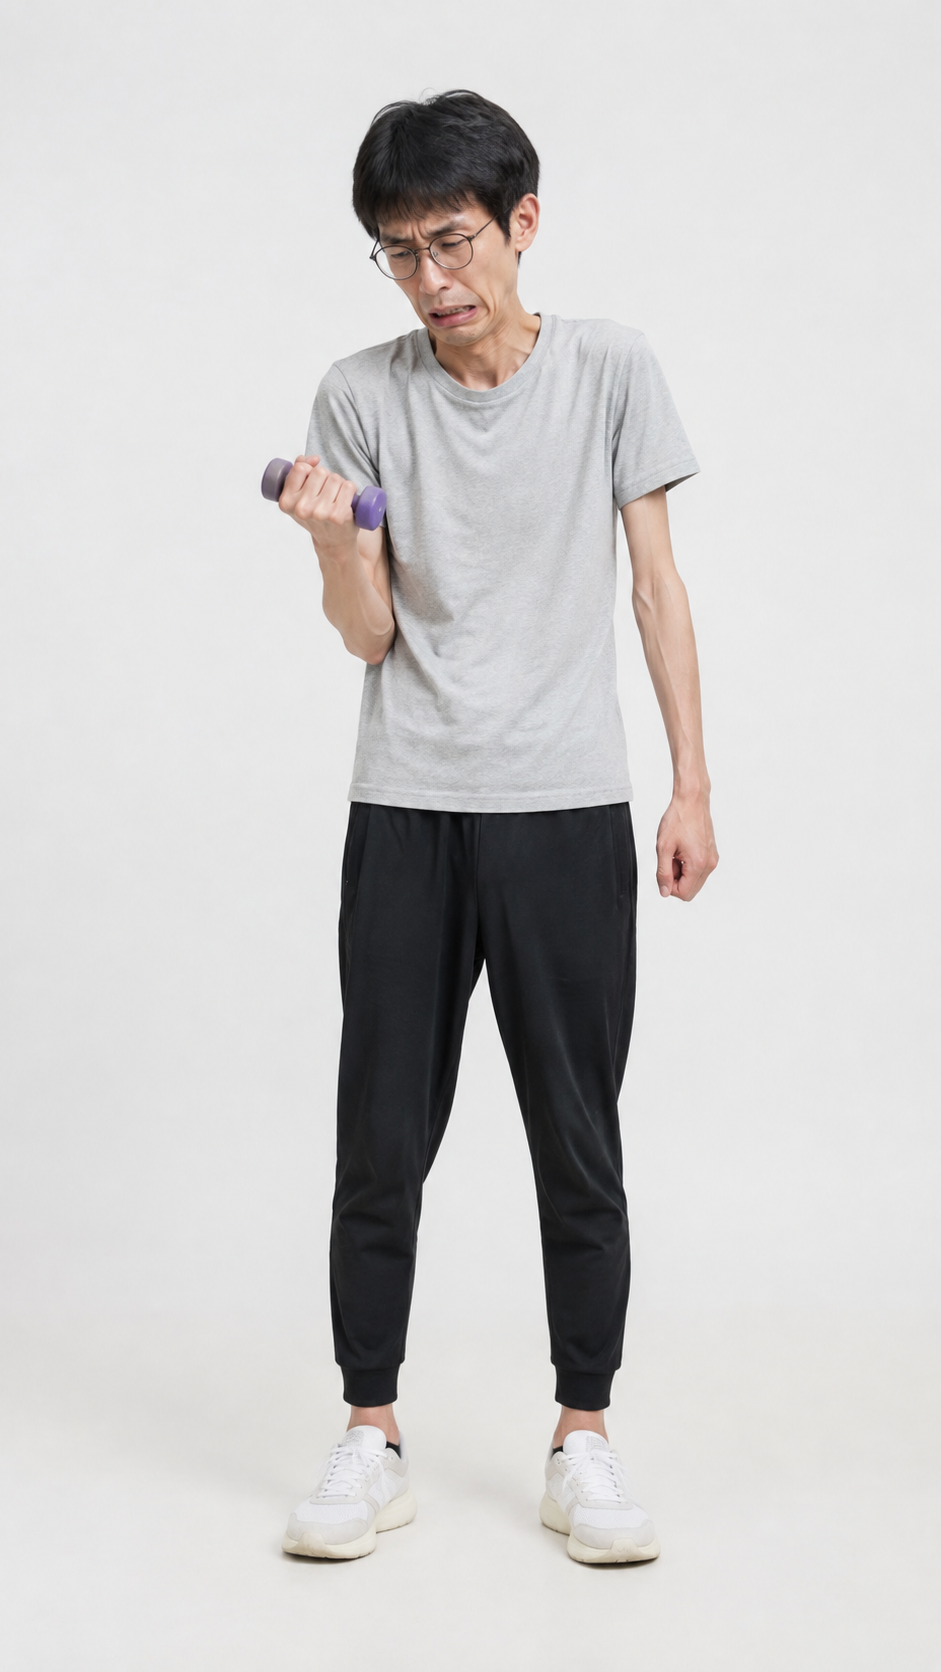
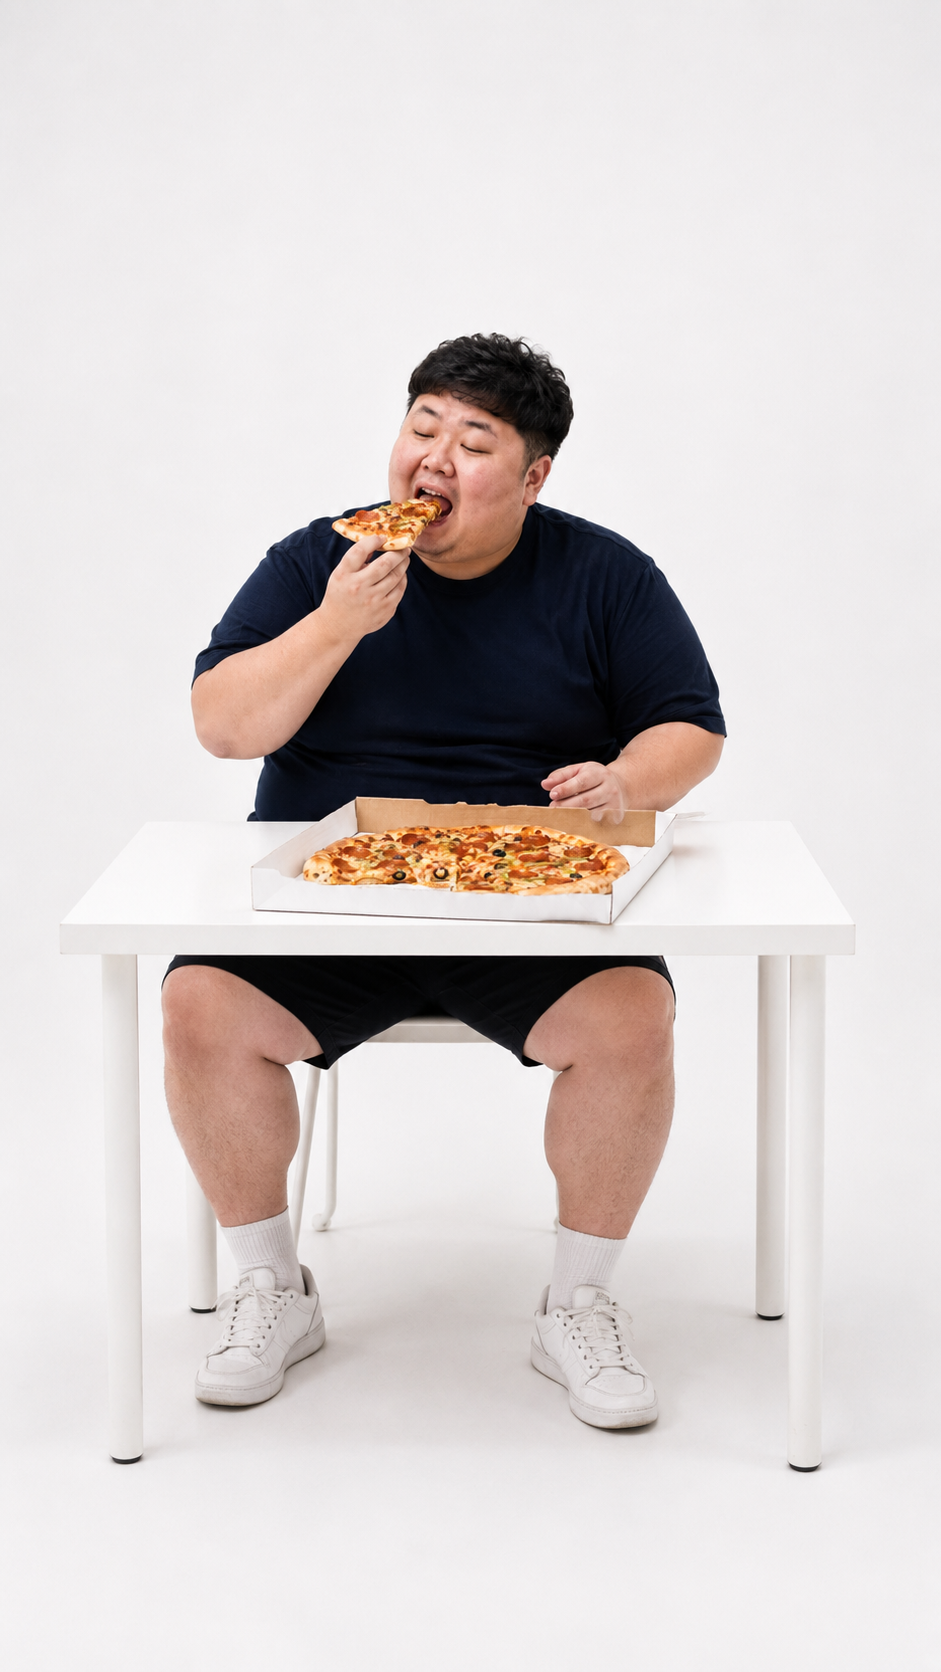
이 소스들은 모두 GPT IMAGE2를 이용해서 뽑아냈습니다. 프롬프트는 아래와 같습니다.
PROMPT
REFERENCE ROLES: @[Image 1](image_1) defines only the identity, face, hairstyle, muscular body, black fitted athletic T-shirt, black shorts, white socks, and white training shoes of the MAIN TRAINER. The collage shows multiple views of the same man. Generate exactly one trainer, never multiple copies, and do not reproduce the collage layout. @[Image 2](image_2) defines only the thin Korean man with glasses, gray T-shirt, black pants, white shoes, strained facial expression, and small purple dumbbell. @[Image 3](image_3) defines only the separate overweight Korean man eating pizza at a white table. He is not the transformation client. @[Image 4](image_4) defines only the Korean woman, her gray athletic top, navy leggings, ponytail, and the black leg-extension machine. @[Image 5](image_5) defines the transformation client before training: an overweight Korean man wearing a black T-shirt, black shorts, white socks, and white shoes. @[Image 6](image_6) defines the same transformation client after training: the identical man now slim and healthy-looking, wearing the same black athletic outfit and white shoes. @[Image 5](image_5) and @[Image 6](image_6) are two states of one person and must never appear together. @[Image 7](image_7) defines only the architecture, black-and-warm-gold lighting, glass entrance, and exact “스스로GYM” facade at the far-right end of the studio. Do not inherit the vertical framing or blank margins of the reference images. GOAL: Create a realistic premium fitness advertisement filmed as one genuine, uninterrupted lateral tracking shot inside one enormous, plain white cyclorama studio. The trainer continuously travels from left to right, naturally addresses the camera in Korean, resolves each fitness problem, and finally enters 스스로GYM. SPATIAL LAYOUT: The entire set already exists as one continuous horizontal space. From left to right: an empty introduction area, a dumbbell station, a white pizza table, a leg-extension station, an opaque floor-to-ceiling white curtain portal, and the full-size black 스스로GYM entrance. Every supporting character remains at their assigned station and begins acting only when the trainer reaches them. The white studio remains unchanged throughout. Do not invent additional rooms or backgrounds. CAMERA: Begin with an eye-level medium-wide shot of the trainer facing the camera. Use one smooth mechanical lateral tracking movement toward the right, parallel to the trainer’s walking path and moving at his walking speed. Keep the trainer clearly visible while revealing each station naturally. Maintain realistic full-body proportions and readable physical interactions. The camera movement never stops abruptly. No cuts, no jump cuts, no montage, no dissolve, no teleportation, no zoom, no orbit, no crane movement, no handheld shake, and no speed ramp. PERFORMANCE AND EVENT ORDER: Stage 1 — Introduction: The trainer stands in the empty white studio, looks directly into the lens with a confident but friendly expression, and says clearly in natural Korean: “저는 스스로GYM의 트레이너입니다.” Pronounce “GYM” naturally as the Korean word “짐.” After finishing the sentence, he turns slightly and begins walking toward the right. The camera starts tracking with him. Stage 2 — Dumbbell assistance: The trainer reaches @[Image 2](image_2), who is struggling to perform a right-arm dumbbell curl. The thin man grimaces and cannot raise the dumbbell past the halfway point. The trainer steps slightly behind his right shoulder. With one hand he supports the man’s forearm, and with the other hand he gently supports the underside of the dumbbell. Together they complete one controlled curl. While helping him, the trainer looks briefly toward the camera and says: “당신을 진정한 남자로 만들어드릴 수 있죠.” The trainer releases the arm only after the dumbbell is stable, then immediately continues walking right. Stage 3 — Pizza intervention: The trainer reaches @[Image 3](image_3), who is seated at a white table and is about to bite one pizza slice. One open pizza box rests on the table. Before the bite occurs, the trainer cleanly takes the single slice from the man’s hand, places it inside the pizza box, closes the lid firmly, lifts the closed box, and tosses it safely offscreen behind him toward frame-left. The pizza box remains closed and does not reappear. The seated man lowers his head onto his folded arms on the table. His shoulders shake slightly as he quietly sobs in comic disappointment. Without stopping for long, the trainer faces the camera and says: “올바르지 못한 습관도 고쳐드립니다.” He continues walking right. Stage 4 — Leg-extension correction: The trainer reaches @[Image 4](image_4). The woman is sitting incorrectly on the leg-extension machine with her hips too far forward and her lower back separated from the backrest. The trainer approaches from the side. With respectful professional contact, he gestures toward the backrest, guides her shoulders and upper back backward, and helps her slide her hips fully into the seat. Her back becomes firmly aligned with the backrest. Her knees align with the machine pivot, and her lower shins rest correctly against the roller pad. She then performs one slow, controlled leg extension with correct posture. The trainer looks toward the camera and says: “운동자세도 제대로 잡아드리죠.” He continues walking right. Stage 5 — Curtain transformation: The trainer meets the overweight transformation client from @[Image 5](image_5). The trainer takes his hand and leads him toward the opaque white curtain portal. Before they pass behind the curtain, the trainer says: “제가 변화시킨 분들만” Both men pass naturally behind the curtain. The camera continues its uninterrupted rightward tracking movement. The curtain briefly and completely hides the client, creating a practical in-camera transformation. The trainer emerges from the other side still holding one man’s hand, but the client is now the slim, healthy-looking version defined by @[Image 6](image_6). Do not show a visible body morph. @[Image 5](image_5) disappears completely behind the curtain, and only @[Image 6](image_6) exits. As they emerge, the trainer completes the sentence: “100명이 넘어갑니다.” The trainer and the transformed member exchange one confident handshake. The transformed man stays beside the curtain while the trainer releases his hand and walks onward. Stage 6 — 스스로GYM entrance: The full-size black-and-gold 스스로GYM facade from @[Image 7](image_7) stands at the far-right edge of the same white studio. As the trainer approaches the glass entrance, he turns his face toward the moving camera and says warmly and clearly: “건강해지고 싶다면 스스로GYM으로 오세요.” He reaches the entrance, opens the glass door naturally, and walks inside 스스로GYM. The camera slows into a stable final composition showing the trainer entering, the open doorway, the premium dark gym interior, and the illuminated “스스로GYM” sign. Hold this final image briefly. AUDIO: All dialogue is spoken directly by the trainer on camera in a clear, natural Korean male voice with accurate lip synchronization. Deliver every sentence exactly once and in the specified order. Do not overlap dialogue. All supporting characters remain naturally silent. Ambience: subtle large-studio room tone. Sound effects: soft footsteps, a light dumbbell clink, pizza-box closing sound, a soft offscreen box landing, quiet comic sobbing, gentle leg-extension machine movement, curtain rustle, and the glass door opening. No background music. No narration. No subtitles. No captions. CONTINUITY AND LOCKS: Preserve the trainer’s @[Image 1](image_1) face, hairstyle, muscular proportions, clothing, and identity throughout the full shot. Exactly one trainer exists. Keep every supporting character separate. Never merge faces, exchange clothes, duplicate bodies, or transfer one character’s appearance to another. @[Image 3](image_3) is only the pizza eater and never transforms. @[Image 5](image_5) and @[Image 6](image_6) are one transformation client shown sequentially, never simultaneously. Keep exactly one dumbbell, one pizza slice being handled, one pizza box, one leg-extension machine, one curtain portal, and one gym entrance. Maintain realistic hand contact, body weight, object physics, walking pace, equipment movement, and door movement. The only permitted visible writing is the “스스로GYM” sign inherited from @[Image 7](image_7). No random text, subtitles, watermarks, additional logos, extra people, extra limbs, fused hands, disappearing objects, costume changes, or background changes.
2) 패션쇼: 멀티 레퍼런스 활용
힉스필드의 가장 큰 강점 중 하나는 최대 50개까지 멀티렌퍼런스를 넣을 수 있다는 거죠. 그 기능으로 만들었습니다. 패션쇼 영상을.
이번에는 장소 사진 포함 총 8장의 사진을 앵커링하여 만들었습니다. 프롬프트를 보실까요?
PROMPT
REFERENCES: @[Image 1](image_1) is the exact runway venue reference. Preserve its runway shape, architecture, floor material, lighting, background, spatial proportions, color palette, and overall atmosphere. @[Image 2](image_2) is Model1. @[Image 3](image_3) is Model2. @[Image 4](image_4) is Model3. @[Image 5](image_5) is Model4. @[Image 6](image_6) is Model5. @[Image 7](image_7) is Model6. @[Image 8](image_8) is Model7. Each model reference controls only that model's exact adult identity, face, hairstyle, skin tone, body proportions, outfit, footwear, and accessories. Do not transfer facial features, clothing, hairstyles, footwear, or accessories between models. OUTPUT: 15-second vertical high-fashion runway film, 9:16. Designed for Instagram Reels, TikTok, and YouTube Shorts. Dynamic editorial montage with cinematic hard cuts, varied camera angles, realistic runway movement, crisp garment details, and consistent lighting. Keep every solo model vertically centered. Preserve complete full-body visibility whenever specified, including the head, outfit, legs, and footwear. Do not crop the head or feet during full-body shots. CAST AND ORDER: Exactly seven adult fashion models. The models appear in strict order from Model1 through Model7. Each model walks individually toward the camera on the same runway. Show only one featured model at a time until the final group shot. Do not omit, duplicate, merge, replace, or reorder any model. Do not transform one model into another. Every model change must happen through a clean cinematic hard cut. TIMELINE: 0.0-0.8s: Begin with a dramatic high bird's-eye establishing shot of the exact runway venue from @[Image 1](image_1). The camera makes a short, controlled vertical descent toward the runway. Emphasize the runway geometry while preserving the vertical 9:16 composition. Do not introduce any featured model before the first hard cut. 0.8-2.4s: Hard cut to Model1 from @[Image 2](image_2) walking toward the camera. Use a low-angle frontal full-body tracking shot. The camera moves backward at the same speed as the model. Create a powerful runway entrance while keeping the complete outfit and footwear clearly visible. 2.4-4.0s: Hard cut to Model2 from @[Image 3](image_3) walking toward the camera. Use a clean side-profile lateral tracking shot. The camera travels parallel to the model while preserving a readable full-body silhouette. Show realistic garment movement, natural footsteps, and the exact outfit from @[Image 3](image_3). 4.0-5.6s: Hard cut to Model3 from @[Image 4](image_4) walking toward the camera. Begin with an eye-level frontal medium-full shot. Perform a short controlled camera push-in. During the final 0.4 seconds, hard cut to an 85mm-style tight facial close-up showing the exact face, expression, makeup, hairstyle, and accessories from @[Image 4](image_4). 5.6-7.2s: Hard cut to Model4 from @[Image 5](image_5) walking toward the camera. Use a floor-level three-quarter low-angle composition. The camera remains close to the runway surface as the model approaches and passes near the lens. Emphasize the footwear, lower garment movement, and complete silhouette. Use realistic perspective without fisheye distortion. 7.2-8.8s: Hard cut to Model5 from @[Image 6](image_6) walking along the runway. Use a direct overhead bird's-eye tracking shot. The camera moves above the model while following the walking direction. Keep the model clearly separated from the runway background. Preserve the recognizable hairstyle, outfit shape, and body proportions from @[Image 6](image_6). 8.8-10.4s: Hard cut to Model6 from @[Image 7](image_7) walking toward the camera. Begin with a close side-profile tracking composition. Move alongside the model with controlled cinematic motion. During the final 0.4 seconds, hard cut to a tight facial close-up. Preserve the exact facial structure, skin tone, hairstyle, makeup, expression, and accessories from @[Image 7](image_7). No facial distortion or identity change. 10.4-12.0s: Hard cut to Model7 from @[Image 8](image_8) walking directly toward the camera. Use a centered head-on telephoto runway shot with subtle lens compression. The camera slowly tracks backward while maintaining strong eye contact. Finish with a confident medium-full hero composition. Keep the complete outfit readable and preserve the exact identity, hairstyle, footwear, and accessories from @[Image 8](image_8). 12.0-15.0s: Hard cut to a dramatic vertical runway finale. Show all seven distinct models from @[Image 2](image_2) through @[Image 8](image_8) together inside the exact runway venue from @[Image 1](image_1). Arrange the models in staggered depth along the runway, not in a wide horizontal line. Front-to-back order: Model7 is closest to the camera. Model6 stands behind Model7. Model5 stands behind Model6. Model4 stands behind Model5. Model3 stands behind Model4. Model2 stands behind Model3. Model1 is farthest from the camera. Offset each model slightly left or right in an alternating formation so that every face and outfit remains clearly visible. Do not allow the models to overlap or block one another. The camera performs a short smooth crane rise into a high-angle vertical composition, revealing the runway geometry and all seven models. The models hold coordinated high-fashion editorial poses. Hold the final stable frame for 0.6 seconds. CAMERA AND EDITING: Use clean cinematic hard cuts and match-on-motion editing. Include: high bird's-eye establishing shot, low-angle frontal tracking shot, side-profile tracking shot, eye-level push-in, tight facial close-up, floor-level three-quarter shot, direct overhead tracking shot, telephoto hero shot, and high-angle group finale. Use one controlled camera movement per shot. Camera movement must be smooth, intentional, and physically plausible. Brief speed ramps may appear only between shots. Do not apply speed ramps, excessive motion blur, or whip transitions over faces, outfits, hands, or footwear. No morph transitions. No continuous transformation between models. No spinning camera. No uncontrolled orbit. No fisheye lens. No chaotic handheld movement. No artificial camera shake. ACTION: Every model performs a confident and natural runway walk. Use subtle individual gestures: controlled eye contact, slight head turn, small hand adjustment, natural coat or fabric movement, or a brief pose at the runway mark. Keep all gestures restrained and editorial. The clothing and each model's individual identity remain the visual focus. STYLE: Premium international fashion-week editorial film. Bold, rhythmic, sophisticated, polished commercial styling. Dynamic but controlled fashion-film direction. Realistic skin texture. Natural facial proportions. Realistic walking physics. Detailed fabric texture. Clean highlights. Controlled contrast. Sharp outfit separation. Consistent color grading across every shot. Preserve the lighting style and atmosphere from @[Image 1](image_1). Do not change the runway into a different venue between shots. AUDIO: Energetic modern runway beat synchronized with the hard cuts. Clear heel and footstep impacts. Subtle camera shutter accents. Natural runway ambience. No dialogue. No vocals. No narration. IDENTITY AND WARDROBE LOCKS: Preserve every model's exact adult identity, face, hairstyle, skin tone, body proportions, outfit, footwear, and accessories from the assigned image. One model reference equals one unique person. @[Image 2](image_2) must always remain Model1. @[Image 3](image_3) must always remain Model2. @[Image 4](image_4) must always remain Model3. @[Image 5](image_5) must always remain Model4. @[Image 6](image_6) must always remain Model5. @[Image 7](image_7) must always remain Model6. @[Image 8](image_8) must always remain Model7. Never exchange faces, outfits, hairstyles, footwear, or accessories between models. No duplicate models. No missing models. No hybrid faces. No face swapping. No wardrobe swapping. No hairstyle changes. No body-shape changes. No changing footwear. No extra runway models. No extra limbs. No deformed hands. No distorted faces. No fused bodies. Background audience members may appear only if already present in @[Image 1](image_1). Keep all background people indistinct, stationary, and visually secondary. They must never resemble or replace the seven featured models. SPATIAL LOCKS: Use only the runway venue from @[Image 1](image_1) for every shot. Preserve the exact runway direction, architecture, floor material, lighting, background, scale, and spatial proportions. All camera angles must depict the same continuous physical runway space. Do not generate a different runway for close-ups, side views, overhead shots, or the final group shot. VERTICAL COMPOSITION LOCKS: Maintain a deliberate 9:16 vertical composition throughout the video. Keep the featured model centered or intentionally placed within the vertical frame. Do not accidentally crop the head, hands, legs, outfit, or footwear during full-body shots. In facial close-ups, keep both eyes, the complete face, hairstyle, and important accessories visible. Do not compress all seven models into a narrow horizontal lineup. Use staggered depth for the final group composition. END STATE: End with all seven distinct models visible inside the runway space from @[Image 1](image_1). Maintain the specified front-to-back formation: Model7, Model6, Model5, Model4, Model3, Model2, Model1. Every face and outfit remains visually separated and recognizable. Finish on a stable high-angle 9:16 composition. Hold for 0.6 seconds. No text. No subtitles. No captions. No logos. No watermarks.
힉스필드 Seedance2.5 무제한 사용은?
Seedance2.5 1080p 생성 가능!
seedance 2.5를 33일간 무제한 쓸 수 있는 기능이 있습니다. (아, 수요일 오전 9시까지 가입하시는 분들에 한한 혜택이긴 합니다)
자, 33일 무제한 프로모션은 끝이 났구요. Seedance 2.5를 이제 Higgsfield에서 1080p 풀HD 화질로 사용할 수 있습니다. 프로모션 기간에 새로 가입하면 구독 없이 무료로 체험할 수 있습니다.
언제 마감될지는 모르겠지만 HD급 화질로 만드는데 관심있다면 체크하세요.
지금 보러가기


* 이제 Seedance 2.5를 1080p로 만들 수 있습니다. → updated 0814
* updated 0813 → 장면 구도별 표현까지 PDF파일안에 추가되었습니다. (글 하단)
* updated 08.11 → 가이드라인 PDF 파일이 추가되었습니다. (글 하단)
아무리 좋은 툴이어도 못쓰면 끝이니까.
요즘 seedance 2.5가 완전히 화재라는건 이제 다 아실겁니다. 여러가지 기능들이 추가된만큼. 아주 좋은 평가를 받고 있죠. 대표적 특징만 보면,
위와 같은 강점이 있다고 볼 수 있습니다. 이런 툴로 소상공인은 무엇을 만들어볼 수 있을까요?
이건 어떠세요?
그래서 한 번 생각해봤습니다. 과연, 소상공인 분들이 seedance 2.5로 어떻게 쓸 수 있을까? 그래서 이렇게 제안해봅니다.
저도 2개 정도를 만들어봤습니다. 하나씩 보실까요?
1) 30초 원테이크 광고영상: 헬스장
원테이크 영상입니다. 이 영상은 총 7개의 레퍼런스 이미지를 가지고 만들었죠.
7장의 사진을 레퍼런스로 등록하고, 이 사진들을 하나씩 앵커링하여 프롬프트를 만들었습니다. 앵커링이란, 영상 제작을 위해 소스로 고정하는 과정으로 @를 써서 보통 지정합니다.
이 소스들은 모두 GPT IMAGE2를 이용해서 뽑아냈습니다. 프롬프트는 아래와 같습니다.
2) 패션쇼: 멀티 레퍼런스 활용
힉스필드의 가장 큰 강점 중 하나는 최대 50개까지 멀티렌퍼런스를 넣을 수 있다는 거죠. 그 기능으로 만들었습니다. 패션쇼 영상을.
이번에는 장소 사진 포함 총 8장의 사진을 앵커링하여 만들었습니다. 프롬프트를 보실까요?
힉스필드 Seedance2.5 무제한 사용은?Seedance2.5 1080p 생성 가능!
seedance 2.5를 33일간 무제한 쓸 수 있는 기능이 있습니다.(아, 수요일 오전 9시까지 가입하시는 분들에 한한 혜택이긴 합니다)자, 33일 무제한 프로모션은 끝이 났구요. Seedance 2.5를 이제 Higgsfield에서 1080p 풀HD 화질로 사용할 수 있습니다. 프로모션 기간에 새로 가입하면 구독 없이 무료로 체험할 수 있습니다.
언제 마감될지는 모르겠지만 HD급 화질로 만드는데 관심있다면 체크하세요.
지금 보러가기